Perplexity-Based Detection of Single-Model LLM Output
A reference model's perplexity score reveals whether a document was machine-generated.
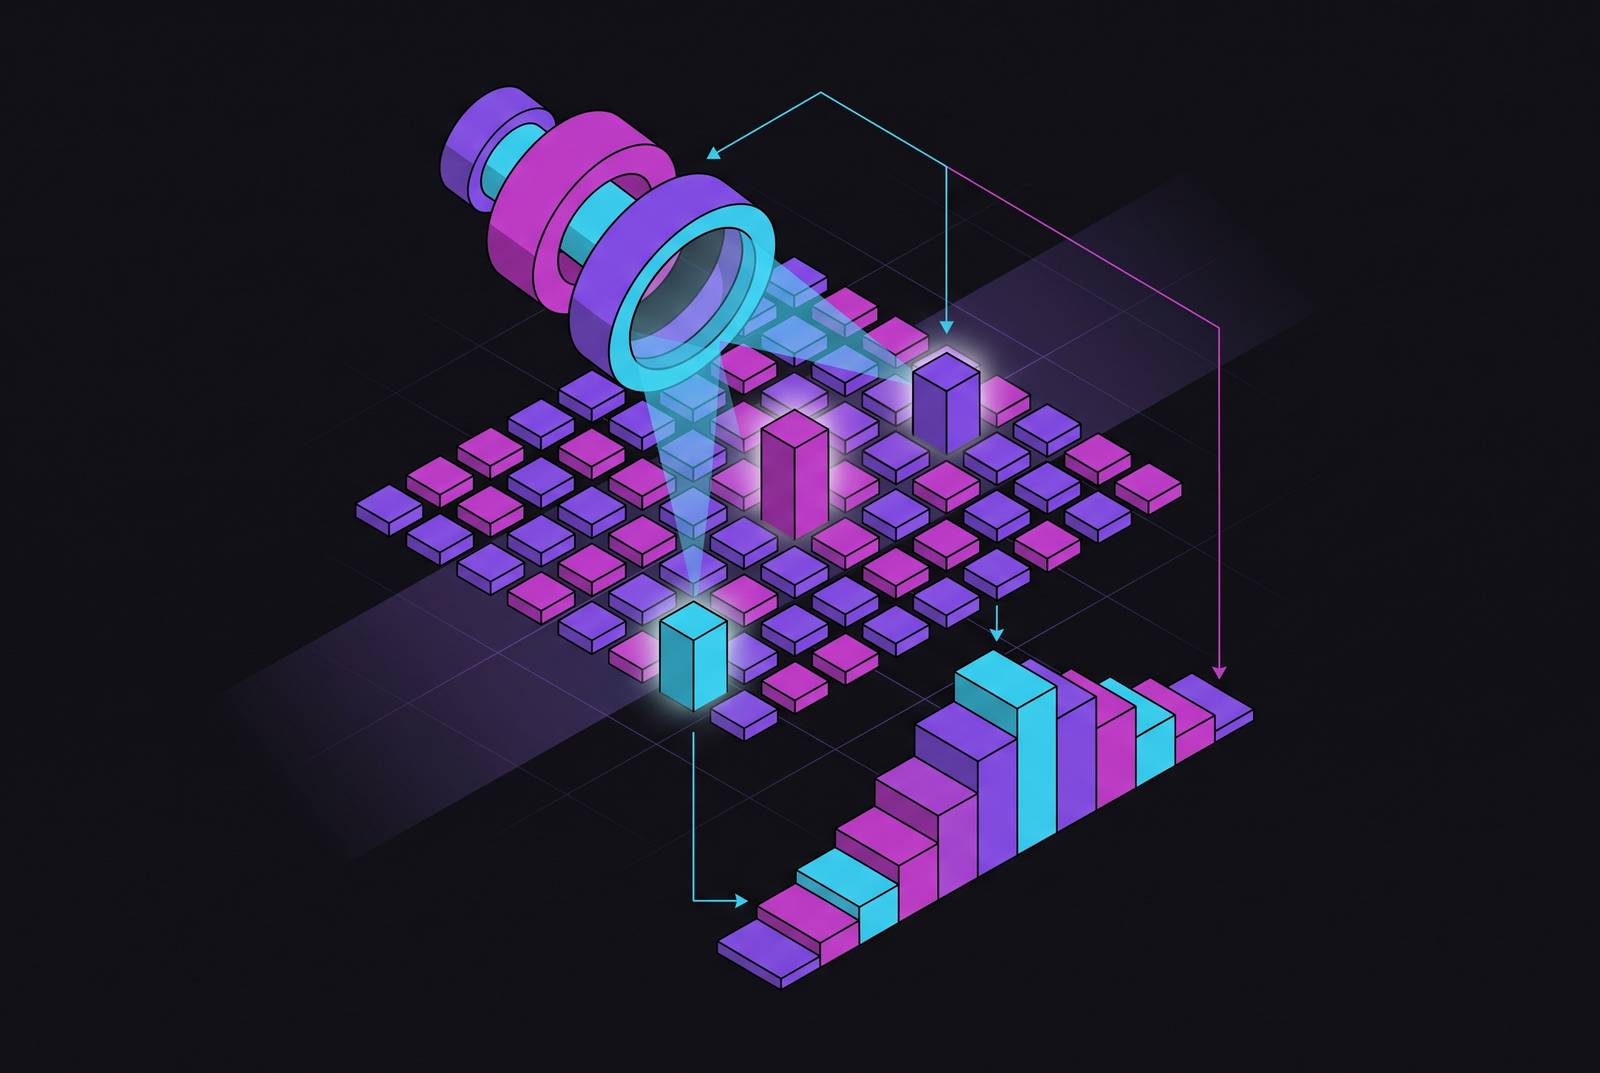
Perplexity is an information-theoretic measure of how well a reference language model predicts a given sequence of tokens. A low perplexity score means the reference model assigns high probability to the tokens it sees, which signals that the text fits comfortably within what that model expects language to look like. A high score means the reference model is repeatedly surprised by what comes next.
Detectors put this measure to work in a specific way. A candidate document gets fed through a reference model, commonly GPT-2, chosen because it is open-source and available for local inference, while many production LLMs either withhold their full token probability distributions or restrict access to them. The reference model doesn't need to be the model that wrote the text. It serves as a proxy for the statistical territory that large language models tend to occupy. If a document sits comfortably inside that territory, scoring low perplexity against the reference, the inference is that it was generated.
The logic depends on a real asymmetry between how people write and how models generate text. Human writing wanders. It takes risks with word choice, doubles back, favors an unexpected phrase over the safe one, and in doing so produces sequences that a language model finds harder to predict. Generated text, by contrast, tends to pick the likely next token far more consistently, and a reference model recognizes that consistency as low surprisal.
The limitation sits in what perplexity collapses in order to produce its answer. It outputs one number, a scalar, for an entire document, averaging token-level likelihood across every sentence regardless of where in the text any unusual phrasing might appear. That number can tell you that a document was "easy to predict" overall, but it cannot show you how predictability moved around within the document, where it spiked, where it dropped, or whether the pattern of fluctuation itself looks like something a single model would produce. That aggregation is exactly where the next layer of the argument begins.
Why a single model's generation process produces a structurally predictable token-likelihood signature
Perplexity catches single-model output because of how autoregressive generation actually works at the mechanical level. Every token an LLM produces comes from sampling a probability distribution that the model computes through a softmax layer, conditioned only on the tokens that came before it. There is no global plan guiding this process, no outline the model is secretly working from. Each token is a local decision, and the model repeats that same local decision procedure at every single position in the document.
That repetition means a model making the same local, greedy-or-stochastic choice at position one also makes it at position one thousand, using the same weights, the same softmax bottleneck, the same absence of long-range planning. The effect is a smoothing of whatever structural variance might otherwise exist across a long document. Human writers vary their rhythm because they're pursuing a communicative goal that spans paragraphs or pages. A model has no such goal; it has only the next token, over and over, and that constancy drives surprisal toward a narrow, predictable band.
This is why generated writing shows less lexical diversity and flatter transitions between ideas than comparable human writing. The variability that marks human prose, the sudden unexpected word, the sentence that takes a turn nobody saw coming, is precisely what an autoregressive sampler is structurally disinclined to produce at scale. Every sentence of a single-model document gets generated by the same process, so the resulting signature is low perplexity in a consistent, repeating pattern that holds across the entire document, because the generation mechanism producing sentence one is identical to the mechanism producing sentence fifty.
This matters because it means the signature is architectural: changing the prompt doesn't change the softmax bottleneck. Asking the model for a different tone, a different register, a different persona, still routes every token through the same sampling procedure, so the statistical fingerprint persists through whatever surface variation the prompt coaxes out. A single model cannot prompt its way out of being a single model.
How modern detectors expose the internal structure of that signature
Because aggregate perplexity only reports a document-wide average, a newer generation of detectors asks a sharper question: not whether average token likelihood is low, but how surprisal behaves as it moves through the text, its variance, its rhythm, its autocorrelation from one token to the next. The underlying signature doesn't disappear when you stop averaging it away. It becomes more visible.
Luminol-AIDetect, developed at the University of Calabria, takes a distinct route to that same internal structure. It applies randomized shuffling to a candidate document and measures how perplexity shifts in response to that disruption. The reasoning behind the method holds that shuffling damages the coherence of LLM-generated text more severely than it damages human-written text, because the coherence in model output is a byproduct of local, token-by-token optimization, while a human author builds structure sentence by sentence through a globally planned process. The resulting dispersion in perplexity-under-shuffling functions as a model-agnostic discriminant: it doesn't require knowing which model produced the candidate text, and it holds up across different domains and languages.
SENTRA, built by researchers at Mozilla Corporation and Ciphero AI, with New York University credited as an author institution, approaches the same underlying signal from a learned angle rather than a hand-crafted one. It encodes selected-next-token-probability sequences, the full run of token-level probabilities produced by feeding a document autoregressively through a reference model, using a Transformer-based encoder trained with contrastive pre-training. SENTRA draws on SNTP sequences from two separate LLMs rather than one, and in out-of-domain evaluations, it outperforms the baselines studied against it, which demonstrates that a learned representation of the full probability sequence generalizes better than heuristic or linear scoring applied to the same underlying input.
What unites Luminol-AIDetect's shuffling approach and SENTRA's learned encoding is the direction of the move, not a ranking between them. Each asks whether the full probability sequence has the shape that single-model generation produces, rather than asking whether the average of that sequence happens to be low. That is a materially harder question for any single model's output to dodge, because it requires the entire token-by-token rhythm of a document to resemble human variability.
KGW Watermarks and the Perplexity-Adjacent Signal
KGW watermarking takes the token-probability layer that perplexity detection already reads and makes it deliberate. At generation time, the scheme derives a hash key from the preceding token, uses that key to split the model's vocabulary into a green list and a red list, and adds a bias, denoted δ, to the logits of every green-list token. Green tokens become statistically more likely to be chosen at each step because the key assigned them that status for that position.
Detection works by counting green tokens across a candidate sequence and comparing that count to a threshold using a z-statistic. A high z-score indicates that the proportion of green tokens is too large to be explained by chance alone, and that excess is read as evidence the watermark is present. This operates on exactly the same statistical layer that perplexity-based detection already inspects: both methods read a signal out of the distribution of tokens in a document, and neither needs to parse what the document actually means.
What separates this watermarking approach from perplexity detection is timing and intent. The watermark gets embedded at the moment of generation, not applied afterward as a label stapled onto finished text. Every sentence a watermarked model produces carries the green-list bias throughout, not selectively in a few marked passages, which makes the scheme function as a provenance mechanism as much as a detection mechanism. It doesn't just flag that some model generated the text. It asserts, with cryptographic grounding, which model did.
That same grounding carries the scheme's weakness. A watermark lives in the tokens themselves, in which specific words were chosen at which specific positions. Paraphrasing a watermarked document, translating it, or rewriting it in different language disturbs the token sequence enough to degrade the green-list statistics, because the cryptographic signal rides on the surface tokens rather than on anything deeper in the document's meaning. The watermark is robust against casual copying but fragile against anyone willing to rewrite.
Why stylometric fingerprinting confirms individual models leave distinguishable signatures
The signature single models leave behind comes entirely from surface linguistic patterns. A study published in Frontiers in Artificial Intelligence, led by Wataru Zaitsu and Mingzhe Jin, examined Japanese text generated by six separate large language models and found that each model could be distinguished from the others through stylometric features: function-word unigrams, part-of-speech bigrams, and recurring phrase patterns. These are surface-level linguistic habits, not probability distributions, and they still carried enough signal to separate one model's output from another's with consistency.
That finding extends the argument well past perplexity and past watermarking. Each model's combination of training data, architecture, and alignment process leaves it with a consistent linguistic fingerprint across everything it produces, independent of whatever cryptographic or probabilistic layer a detector might also be reading. A model doesn't need to embed a watermark to be identifiable. Its habitual word choices and syntactic patterns already give it away.
The consequence for anyone running content through a single model is more serious than simple detectability. Stylometric fingerprinting pushes the question from a binary of human versus AI into something closer to attribution: not just whether a document was generated, but which specific model generated it. A content pipeline built entirely on one model is identifiable as that particular model's output, with real confidence, from surface patterns a watermark scheme would never need to supply.
The Frontiers study worked from a known candidate set of six models and from Japanese-language text specifically, and stylometric fingerprinting of this kind assumes an investigator is choosing among a defined list of candidate sources. When the source model is unknown, or when a document draws on more than one model's output mixed together, the fingerprint gets harder to isolate. That boundary condition isn't a flaw in the method so much as a signal of where the argument needs to go next: toward what happens when generation itself stops coming from a single source.
Where single-signal perplexity detection fails
Perplexity-based detection has real, documented limits, and the honest version of this argument has to name them rather than wave past them. One well-known failure mode concerns detector calibration against non-native writing in a given language, which can score with lower perplexity than native writing for reasons that have nothing to do with AI generation, producing false positives against human authors. Another concerns what happens when a detector evaluates a response without the prompt that produced it: without that context, a perplexity check loses a baseline it would otherwise have for judging whether a given level of predictability is unusual. Cross-perplexity methods, including the approach described in the Binoculars paper by Hans and colleagues in 2024, were built specifically to calibrate for cases where prompts are unknown to the detector, computing a ratio between two LLM-derived metrics on the response text alone rather than depending on scalar perplexity against a single reference model.
These are genuine limitations of a single scalar statistic applied naively. They are not evidence that single-model pipelines escape detection. The absence of a prompt only means that a document without its prompt attached might slip past a naive perplexity filter, a narrow condition that doesn't generalize to the way most real content pipelines actually operate, where prompts are logged, stored, and available for exactly this kind of review.
The detection toolkit built in response to these gaps is not standing still. DivEye's surprisal-diversity features, Luminol-AIDetect's perplexity-under-shuffling, and SENTRA's learned SNTP representations each take aim at a different facet of the fragility in naive scalar perplexity, and together they show a toolkit actively expanding past the single-number baseline rather than retreating from it. The single-model token-likelihood signature is a property of how the text was generated, which holds regardless of which specific detector currently catches a given document, and today's detector either notices it or doesn't without changing that fact. A detector that misses a signature can be updated tomorrow. The signature itself, produced by the same softmax bottleneck applied at every token position, doesn't change.
Structural Departure from Single-Model Generation in the Frankentext Paradigm
The strongest confirmation of this entire argument comes from a method built explicitly to defeat detection, succeeding by abandoning single-model generation. Researchers at the University of Maryland and the University of Massachusetts Amherst, including Chau Minh Pham, Jenna Russell, Dzung Pham, and Mohit Iyyer, introduced a paradigm they call Frankentexts: long-form narratives assembled by treating an LLM not as an author but as a composer, stitching together thousands of randomly sampled human-written snippets into a coherent story around a given prompt. In their best configuration, using Gemini-2.5-Pro with 5,000 input snippets, roughly 90 percent of the tokens in the final text are copied verbatim from human sources.
That number demonstrates something more specific than "detectors can be fooled." It demonstrates what it actually takes to fool them.
The mechanism is explicit in the method's own design. Because most of the tokens in a Frankentext are human-written tokens lifted from existing sources, the resulting token-probability distribution, measured against any reference model, no longer has the shape that single-model generation produces. There is no single softmax bottleneck stamping its rhythm across the whole document, because no single model generated the words. The LLM's role shrinks to selection and arrangement, stitching fragments into a narrative, while the actual token-by-token statistics belong to many different human authors at once.
That is the structural proof the rest of this argument has been building toward. Paraphrasing a document, adjusting its tone, running it through a style transfer prompt, none of these change the underlying generation process enough to escape a sufficiently thorough detector, because the tokens are still coming from one model's softmax bottleneck applied over and over. Evasion that actually works requires abandoning single-model generation as the source of the tokens themselves. Frankentexts succeed because they change what is actually being measured: a document built from thousands of human hands no longer carries the one signature perplexity was built to find.
Sources
- Published in Transactions on Machine Learning Research (02/2026)
- Luminol-AIDetect: Fast Zero-shot Machine-Generated Text Detection based on Perplexity under Text Shuffling
- SENTRA: Selected-Next-Token Transformer for LLM Text Detection
- Frontiers
- Frankentext: Stitching random text fragments into long-form narratives