How Judge-Model Selection Affects Final Output Quality in Multi-LLM Pipelines
Choosing the wrong judge model can systematically favor weaker outputs over better ones.
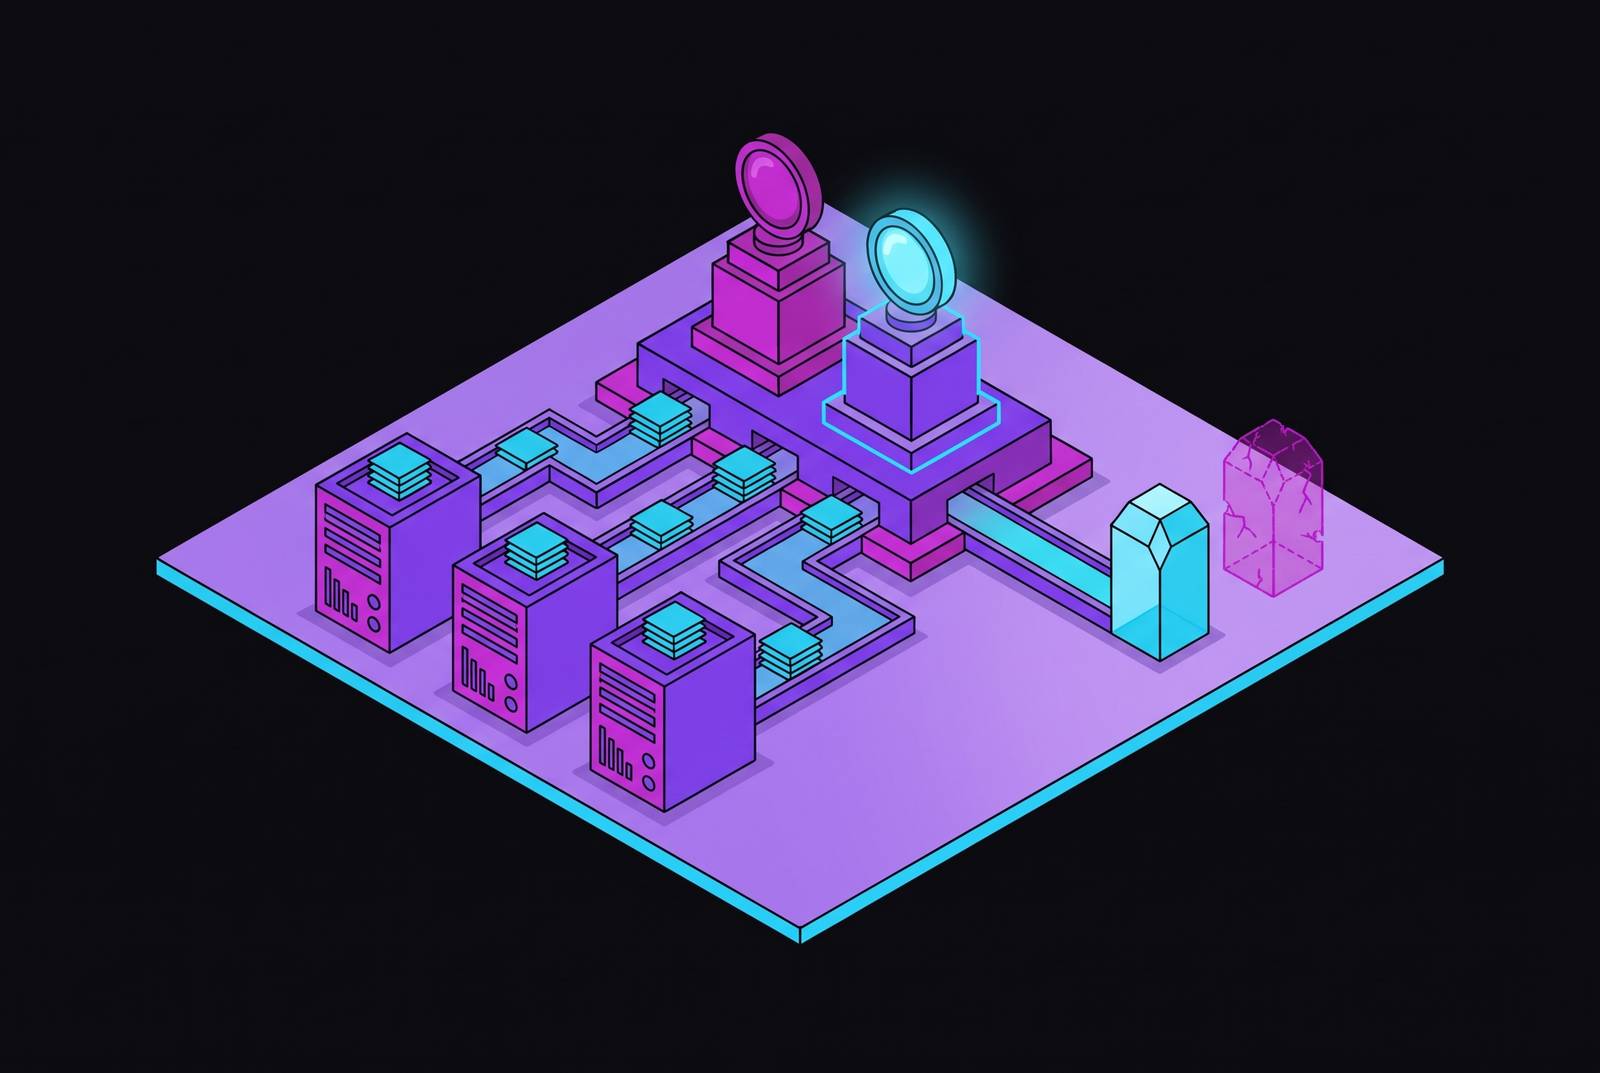
Judge-model selection determines how a multi-LLM pipeline scores outputs and which ones it publishes. The central design principle is that judge independence, scoring rules, and ongoing calibration must work together. Even a capable judge can lead a pipeline to choose familiar phrasing, styles it favors, or longer answers over better content.
Why the judge model is not a neutral measurement instrument
Teams can scrutinize a rubric while treating judge selection as an administrative choice. That distinction fails when the judge reads the rubric, prompt, and candidate response, then returns a structured score and reason shaped by its own training distribution. The score is a measurement of merit that reflects the evaluator’s preferences as well as the candidate’s quality, and the pipeline executes the resulting selection directly.
This gives judge errors immediate downstream consequences. A weak or misaligned evaluator can produce scores that do not predict user feedback, leaving an evaluation suite green while thumbs-down rates rise. Release gates then lose trust because output that passes them may no longer be good enough. The most damaging outcome is false confidence, with an evaluation program present but unable to catch real regressions.
The three systematic biases that drive most of the variance in judge output
Self-preference, style bias, and verbosity bias account for most of the distortion introduced by judge selection. They work in different ways and need different controls. Self-preference occurs when a judge favors responses from its own model family because they resemble its phrasing and style, independently of correctness. Across repeated selections, it systematically advantages one class of candidates over the others.
Style bias extends beyond shared model provenance. A judge may give its preferred sentence rhythm, register, or structure priority over logical soundness and evidential support. In production, stylistic preference is the harder and more pervasive problem than position bias. Rotating response order therefore addresses only part of the problem. It changes where a response appears without changing the stylistic features that attract the judge’s preference.
Verbosity bias gives longer responses an artificial advantage because RLHF training data has historically associated thoroughness with length. More words need not mean more substance. Clear instructions to ignore length and assess claims one by one stop padding from earning a higher score. A further pattern, extremity bias or integer fatigue, pushes judgments toward the ends of an integer scale over repeated evaluations, compressing its useful range. These distortions can remain silent because a single scalar score does not separate logical structure from evidential support.
Why reliability without validity is the dominant failure mode in production judge pipelines
A judge can reproduce its scores without selecting the right candidate. Reliability describes consistency across repeated evaluations of the same input, while validity concerns agreement with actual quality. These are independent properties of an evaluation system. A stable preference for familiar wording can make a judge highly repeatable even as it consistently ranks weaker responses above stronger ones.
Ordinary runtime metrics may not reveal this gap. If every repeated call returns the same verdict, the pipeline appears dependable, but repetition has tested only whether the judge agrees with itself. It has not established whether the selected output deserves publication. To catch these errors, scores must be compared with judgments that meet the intended quality standard.
Cohen’s kappa against a stable human-labeled golden dataset provides that comparison. Consistency remains useful, but it cannot stand in for evidence that scores discriminate on merit. A production pipeline that checks only repeatability can keep making the same wrong choice in every release.
How family independence, not raw capability, is the primary control variable for bias suppression
Family independence is the primary control for self-preference bias. A larger judge from the generator’s family can still inflate scores for same-family responses, because greater capability does not reliably remove that preference. A well-calibrated smaller model from another family may have better validity. The relevant comparison concerns which generators the judge evaluates.
The practical defense is to separate generation and evaluation across model providers so that the judge does not grade its own provider’s output. Style and verbosity preferences can remain even after family overlap is removed. An independent judge must also show that it meets a validity floor before its scores can be trusted.
Frontier judges still do some tasks better. Safety evaluation and multimodal output can require reasoning depth that takes priority over provenance independence. That exception does not establish that the strongest available model is always the best selector for candidate lines or drafts. For those pipelines, the choice of judge should start with family independence and a minimum kappa threshold, ahead of cost or raw benchmark rank.
What scoring rules do to judge bias once a model is selected
Scoring rules can amplify or suppress the preferences of an otherwise suitable judge. The rubric determines what distinctions the model must make, while aggregation determines how those distinctions affect selection. Neither is a cosmetic layer around model choice. Open-ended integer scales invite extremity bias, while binary yes/no checklists give signals that are more stable and easier to compare across evaluation runs.
Evidence before verdict is another useful control. Instructions that require the judge to commit to supporting evidence before scoring make the basis of the decision explicit and auditable, reducing position bias and self-preference. This approach avoids relying solely on swapping response order and discarding inconsistent results, which consumes compute and introduces data-selection bias. Task-specific criteria injection further sharpens discrimination by adding a category-aware criterion to a generic judge prompt. Its added cost is negligible.
RewardBench 2 tests judges across six categories, including Factuality, Focus, Mathematics, Precise IF, Safety, and Ties. Each example presents a query with four candidate responses, which the judge scores from 1 to 10. The benchmark exposes differences across task types. It also makes the interaction between model capability and scoring rules concrete, rather than treating judge quality as one universal property.
Rubric failures can undermine these controls. Showing a gold answer while grading reference-free traits rewards paraphrase rather than correctness, and leaving temperature at its default adds stochastic variation to systematic bias. These failures have different causes, but both weaken the meaning of the final score. Model selection cannot compensate for rules that reward the wrong evidence or introduce avoidable variation.
Ensemble scoring and adaptive escalation as structural remedies, not just mitigations
Ensemble scoring treats per-call noise as a statistical problem. Multiple independent judge completions introduce different stochastic variation, and averaging their scores suppresses that variation through Monte Carlo averaging. This changes the selection architecture rather than relying on a single call to behave consistently. Repeating a biased evaluation can stabilize the wrong preference, so ensembling complements family independence and rubric design.
Lail & Markham’s ICML 2026 paper finds that small models benefit disproportionately from this approach. A mini model at k=8 with criteria injection matches a full-model k=8 ensemble in accuracy at roughly one-quarter the cost.
Adaptive escalation offers a related way to allocate capacity. A smaller proxy judge handles high-confidence cases, while high score variance triggers escalation to a larger model. The same paper finds that escalation improves over baseline but is dominated by criteria injection plus ensembling on the cost–accuracy frontier. It is useful, but not the primary lever. Tiered routing nevertheless addresses the expense of running a frontier judge on every production trace.
High variance distinguishes unstable judgments from cases in which the judge produces a clear signal. Low variance still establishes consistency, so the architectural benefit depends on maintaining the external quality check for validity.
What periodic recalibration requires and why a static judge selection decays
A judge’s validity at selection time is not permanent. Model updates, distribution shift, and training-data changes can alter its behavior while the pipeline continues to trust its scores. The architecture can remain unchanged even as the evaluator’s decisions move away from the intended standard. Recalibration is therefore operational maintenance.
The required signal is Cohen’s kappa against a stable human-labeled golden dataset. A judge that drops below 0.7 kappa should be flagged before it gates another release, regardless of which model version change caused the decline. The threshold anchors trust in measured agreement. It prevents the model’s reputation or previous performance from substituting for current evidence of validity.
Calibration context injection can partly compensate between recalibration runs. Feeding a previously scored reference example into the prompt anchors the judge’s scoring scale. The same paper finds that this technique does better than baseline, though criteria injection plus ensembling does better at about the same cost. An anchor is useful, but it is not a replacement for measuring whether the judge still agrees with the human-labeled standard.
The golden dataset also needs controlled exposure. Using a reference example to anchor a scale has a different purpose from showing a gold answer while the judge assesses reference-free traits. In the latter case, the judge can give resemblance to the answer priority over the quality being evaluated. Holding the golden dataset in reserve preserves its role as an independent calibration standard.
How these mechanisms apply to multi-model content pipelines where selection determines final published output
In a multi-model content pipeline, the judge authors the selection even though generators supply the words. Preferences that shape the judge’s ranking can influence which text the pipeline publishes. This is especially consequential when the system selects individual lines or drafts without subsequent human review. Evaluation quality and output quality are joined at that decision point.
Family independence is harder to achieve when several providers generate candidates. A judge drawn from any participating provider can favor its own family’s output, so independence requires a neutral, non-generating family. Otherwise, a nominally diverse candidate pool can still yield a single-family stylistic signature. The diversity of generation does not establish diversity of selection.
Style bias creates a similar bottleneck without shared provenance. A judge that favors one rhythm or register can suppress useful variation across all generators, while preferences that vary by candidate position or run can produce inconsistent voice. The remedy is an explicit target-voice rubric. It makes stylistic consistency a criterion to assess rather than an implicit preference inherited from the judge’s training.
Scoring architecture then determines how reliably that criterion guides publication. Per-claim assessment limits verbosity rewards, task-specific criteria sharpen relevant distinctions, and repeated scoring exposes uncertain selections for possible escalation. Recalibration checks whether those decisions still agree with the human-labeled standard as models change. These controls address distinct failure modes. Even with these controls, multi-model generation alone does not prove that the final draft is better.
Claims that multi-model output is undetectable need a separate quantitative test. A pipeline must demonstrate that its selector does not reintroduce a single-family signature after diverse candidates have been generated. Qualitative claims about diversity cannot establish that result. Z-score benchmarks against real detectors are the appropriate evidence standard for that claim, making the judge’s effect on final published output measurable.
Sources
- On Cost-Effective LLM-as-a-Judge Improvement Techniques
- Reliability without Validity: A Systematic, Large-Scale Evaluation of LLM-as-a-Judge Models Across Agreement, Consistency, and Bias
- When the Judge Should Not Decide: Evidence-Locked, Non-Compensatory Selection Bounds LLM-Judge Failure in Reasoning Pipelines